Alex Kargin

Data & AI Engineer

About Me

I’m Alex Kargin, a Senior Data and Analytics Engineer based in Boca Raton, Florida. I have built and supported production data systems since 2013—currently as a contract Data Engineer at Silicon Army, previously at Restaurant Brands International / Burger King and, before that, nearly six years at Orangetheory Fitness.

A recurring thread through that work is migration and modernization. At Orangetheory I led the move from Aurora and Redshift to Snowflake—source-system analysis, schema and data mapping, transformation logic, cleansing, reconciliation, validation, and cutover. Earlier database engineering roles covered migrations across MySQL, PostgreSQL, SQL Server, and Aurora, along with query tuning, OLTP-to-OLAP modeling, and production support through DEV/SIT/UAT/Production release workflows.

I build data solutions end to end—from raw operational data and complicated business rules to trusted Snowflake models, Power BI dashboards, APIs, and production AI applications.

A lot of that modeling is what the industry now calls the semantic layer: defining metrics and business logic once, in the warehouse, so dashboards, applications, and AI agents all read the same numbers instead of each re-deriving them from raw source systems. It is the same dimensional modeling and dbt work I have been doing for years, pointed at a new consumer—something I wrote about recently after dbt Labs reported cutting AI token costs ~98% by feeding agents modeled summaries rather than raw source data.

My experience combines data engineering, analytics engineering, business intelligence, and applied AI. I work across Snowflake, dbt, Dagster, Airflow, Power BI, Python, SQL, AWS, Azure, PostgreSQL, ClickHouse, FastAPI, and Next.js.

I have delivered analytics solutions supporting Finance, Accounting, Operations, Marketing, forecasting, and executive reporting. My work includes dimensional modeling, semantic models, DAX, KPI development, data-quality validation, cloud migrations, performance optimization, governance, and production support.

I also build practical AI systems, including document intelligence, RAG, vector search, NLP, computer vision, and private LLM applications. My focus is not AI for demonstration purposes—it is using the right technology to solve a real business problem reliably, securely, and cost-effectively.
Experience

Silicon Army — Data Engineer (Contract)

Apr 2026 – Present · Remote / New York

  • Built ingestion pipelines connecting email, forms, documents, CRMs, accounting systems, ERPs, databases, and APIs to AI-enabled workflows.
  • Modeled and normalized operational data into reliable structures consumed by AI agents rather than exposing raw source systems.
  • Built retrieval-ready RAG datasets with chunking, metadata, source identifiers, timestamps, permissions, and embeddings; implemented RBAC-aware retrieval controls.
  • Built audit and event pipelines capturing agent actions, tool calls, approvals, failures, latency, token usage, and cost; implemented pre-execution data-quality controls including duplicate detection, reconciliation, and totals validation.
  • PostgreSQL, ClickHouse.

Restaurant Brands International / Burger King — Data Engineer

May 2025 – May 2026

  • Built and maintained production Snowflake, dbt, and Dagster pipelines supporting operational KPIs and BK Insights reporting.
  • Delivered store-level ingredient-demand forecasting at 30-minute intervals.
  • Owned lineage, observability, production support, and performance/cost optimization.
  • Snowflake, dbt, Dagster, Python, SQL.

Orangetheory Fitness — Senior Data Engineer

Mar 2021 – Apr 2025

  • Led Aurora/Redshift to Snowflake modernization and migration.
  • Built Finance and Accounting analytics including reconciliation, data quality, and invoice exception detection.
  • Owned governance, RBAC, and secure data sharing; performance optimization; mentoring.
  • Snowflake, dbt, Streams/Tasks, Airflow, Python, SQL.

Orangetheory Fitness — Cloud Database Engineer

May 2019 – Mar 2021

  • Database migrations and ETL/ELT development across MySQL, PostgreSQL, SQL Server, Aurora, and Redshift.
  • Production support across DEV/SIT/UAT/Production workflows.
  • AWS, Azure DevOps, Power BI.

InnovaTek Solutions Inc. — Founder / Technical Lead

Feb 2020 – Present

  • Independent data, analytics, AI, and web application work, concurrent with full-time employment.
  • Projects listed in the Portfolio section below.

Lenovo / Management Maintenance Inc. — Database Engineer

2015 – Apr 2019

  • SQL database development, OLTP to OLAP modeling, query tuning, and validation.
  • Power BI reporting; AWS Lambda and Python automation; production support.

LiveIntent — Database Analyst / Developer

2013 – 2015

  • Analysis of large advertising datasets: impressions, clicks, conversions, CTR, CPM, ROAS.
  • Client scorecards, reconciliation, and anomaly investigation.

Education & Certifications

  • Master’s Degree, Computer Science — Grozny State University, 2003
  • SnowPro Core Certification — Snowflake

Skills

  • Analytics & Business Intelligence: Power BI, DAX, semantic models, KPI development, dashboards, data visualization, executive reporting, data reconciliation
  • Data Engineering: Snowflake, dbt, Dagster, Airflow, ETL, ELT, data pipelines, workflow automation, dimensional modeling, semantic layer, metric definitions, star schemas, slowly changing dimensions
  • Data Migration & Modernization: data migration, data conversion, legacy modernization, source-system analysis, schema mapping, data mapping, transformation logic, data cleansing, reconciliation, validation, iterative migration cycles, cutover, go-live support, Aurora, Redshift, MySQL, SQL Server, PostgreSQL
  • Snowflake Platform: Snowflake, SnowPro Core certified, warehouse sizing, resource monitors, Streams and Tasks, RBAC, secure data sharing, masking, cost optimization, performance tuning
  • Database Engineering & Production Support: database administration, query tuning, index optimization, stored procedures, OLTP and OLAP modeling, database migrations, production support, incident triage, root cause analysis, troubleshooting, DEV/SIT/UAT/Production release workflows
  • Programming & Databases: Python, SQL, PostgreSQL, MySQL, SQL Server, ClickHouse, FastAPI
  • Cloud & Delivery: AWS, Azure, Azure Data Factory, Azure DevOps, GitHub Actions, CI/CD, Docker, Linux
  • Data Governance & Quality: RBAC, masking, lineage, data validation, testing, observability, metadata, performance and cost optimization
  • Applied AI: RAG, grounding, document intelligence, vector search, pgvector, local LLMs, prompt engineering, structured outputs, agent workflows, evaluation harness, NLP, entity extraction, computer vision
  • Application Development: REST APIs, API integration, Next.js, React, TypeScript, JavaScript
  • Delivery & Collaboration: requirements gathering, stakeholder communication, solution design, technical documentation, mentoring, cross-functional delivery with Finance, Accounting, Operations, and Marketing teams

Portfolio

Production data, analytics, business intelligence, and AI systems—from source ingestion and modeling through dashboards, APIs, applications, and deployment.

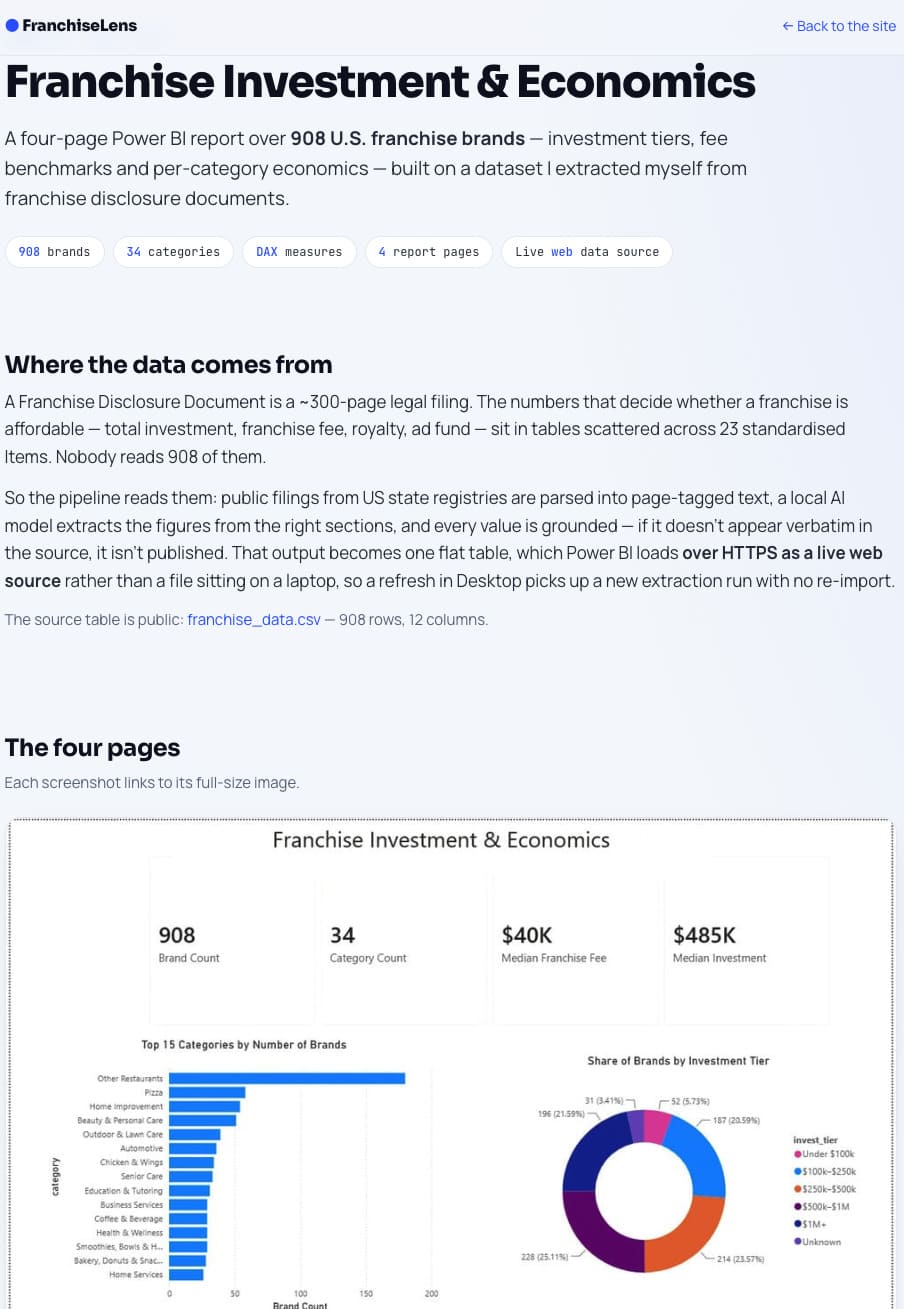
Power BI Franchise Investment & Economics

Power BI Franchise Investment & Economics

Designed and built a four-page Power BI report covering 908 U.S. franchise brands across 34 business categories.

The report transforms franchise disclosure data into interactive investment, fee, and category benchmarks using dimensional modeling, DAX measures, searchable slicers, dynamic sorting, and a live HTTPS data source.

Implemented documented data-quality controls for incomplete disclosures, small sample sizes, duplicate records, missing financial values, and statistical anomalies.

The case study includes report screenshots, analytical findings, technical documentation, and downloadable PBIX files.

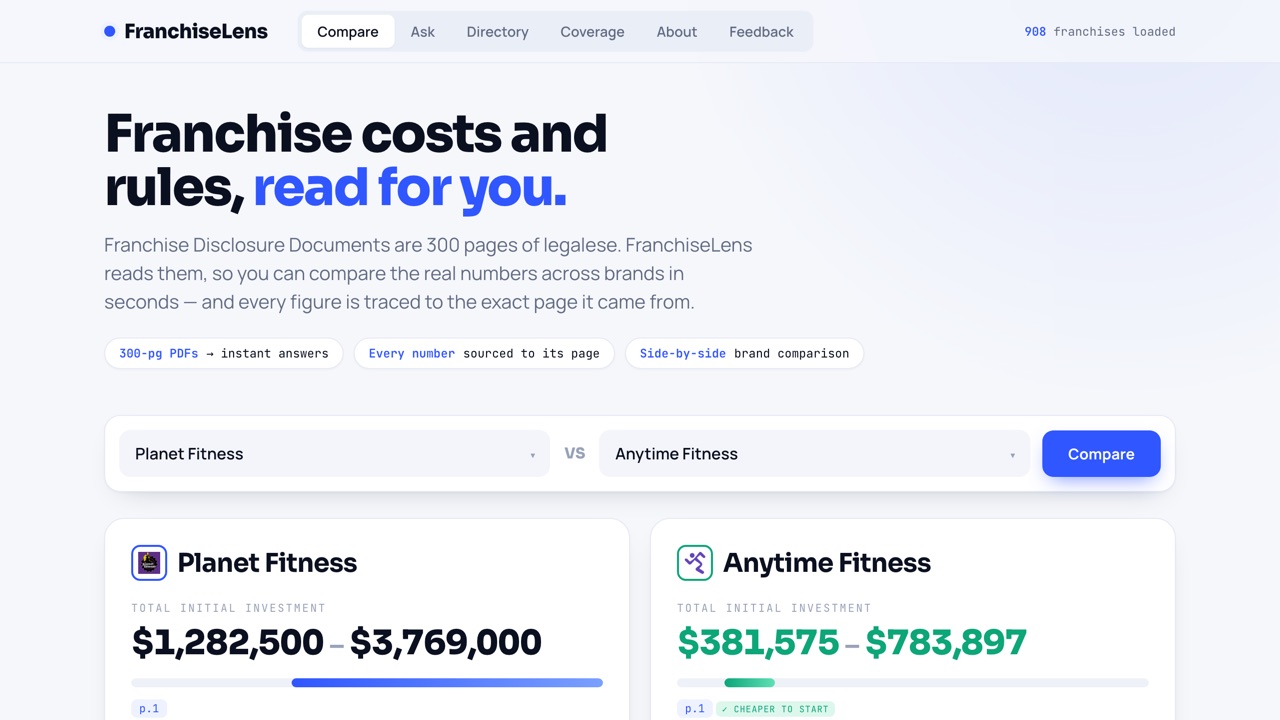
FranchiseLens

FranchiseLens

Document-intelligence engine over public Franchise Disclosure Documents — the ~300-page filings franchisors must register with US states. It pulls filings from state registries and runs a local-LLM extraction pipeline that lifts the numbers buyers actually care about: total initial investment, franchise fee, royalty, ad fund, net-worth and liquid-capital requirements, agreement term, and outlet counts. 908 franchises loaded, with a coverage survey across 65 fitness & sports brands.

Every figure is grounded to the exact page it came from (p.18, p.47…) and flagged for review when it can't be verified — so a side-by-side brand comparison, a natural-language Ask over the documents, and a browsable directory all stay auditable. Runs entirely on self-hosted models, no third-party LLM API.

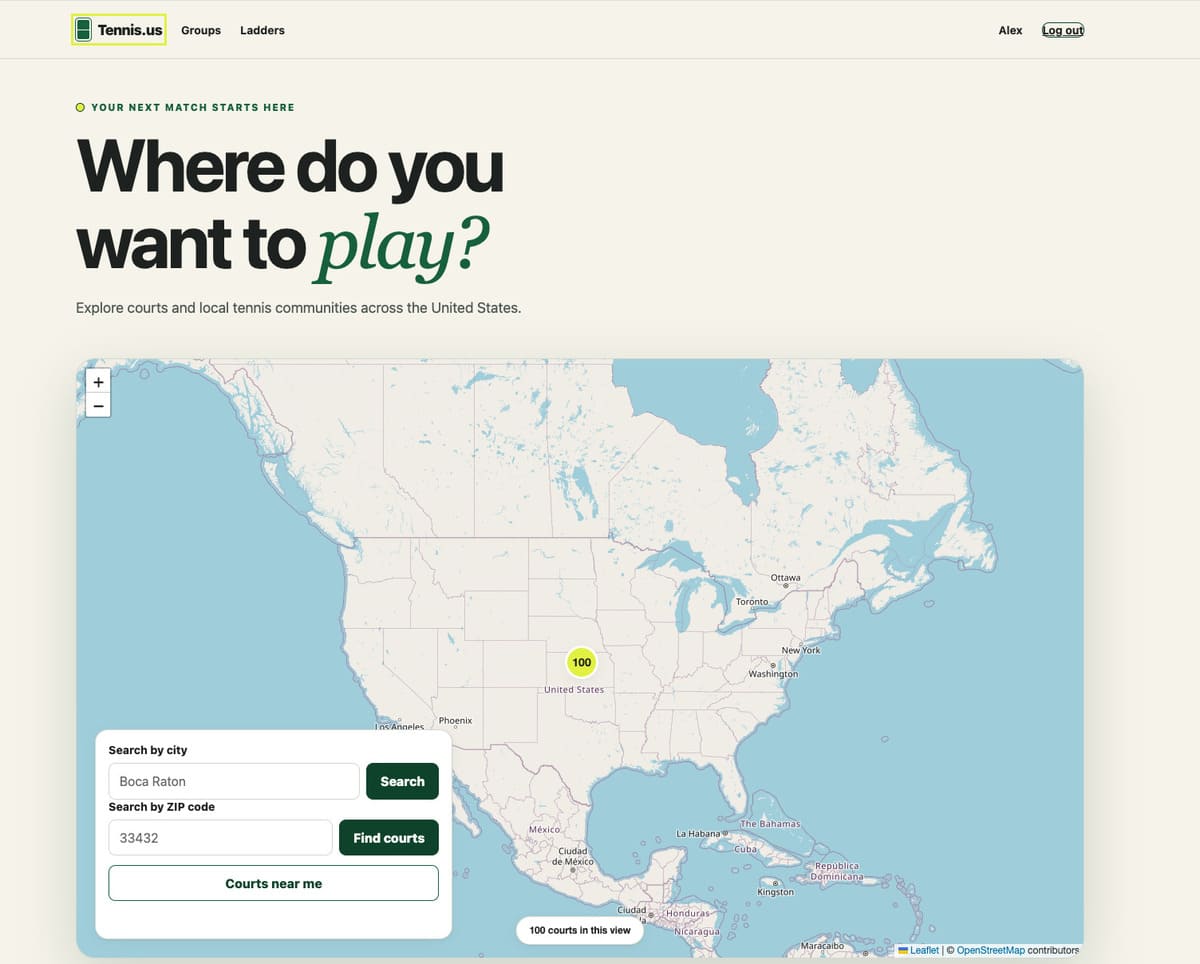
Tennis.us

Tennis.us

AI-powered tennis community platform built across 14 phases. Geospatial venue clustering groups raw court polygons into named venues with addresses and directions; AI player-matchmaking pairs players by level and location; plus ladders, matches, events, and a full design system — on a Next.js/FastAPI stack with production deploy parity.

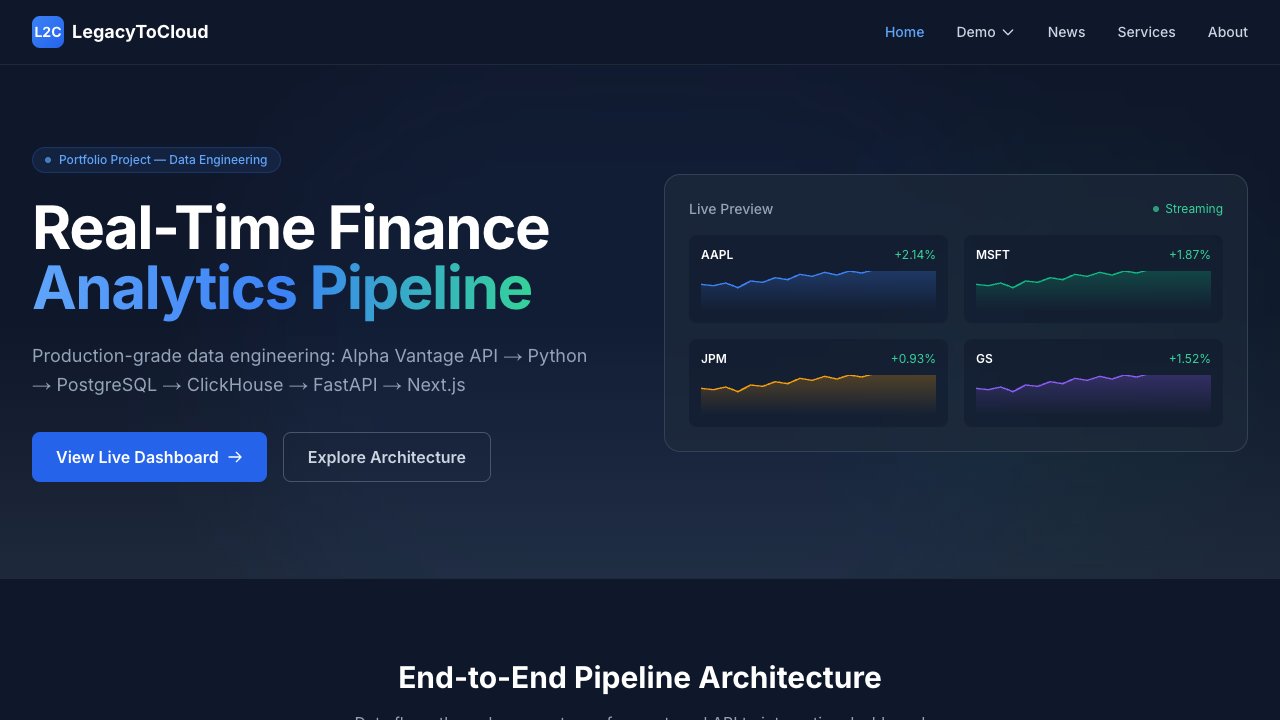
LegacyToCloud

LegacyToCloud.com

Database migration platform that analyzes legacy MySQL/PostgreSQL/MSSQL schemas and generates cloud-ready DDL for PostgreSQL and Snowflake. Includes a real-time financial data pipeline (Alpha Vantage → PostgreSQL → ClickHouse) with interactive dashboards.

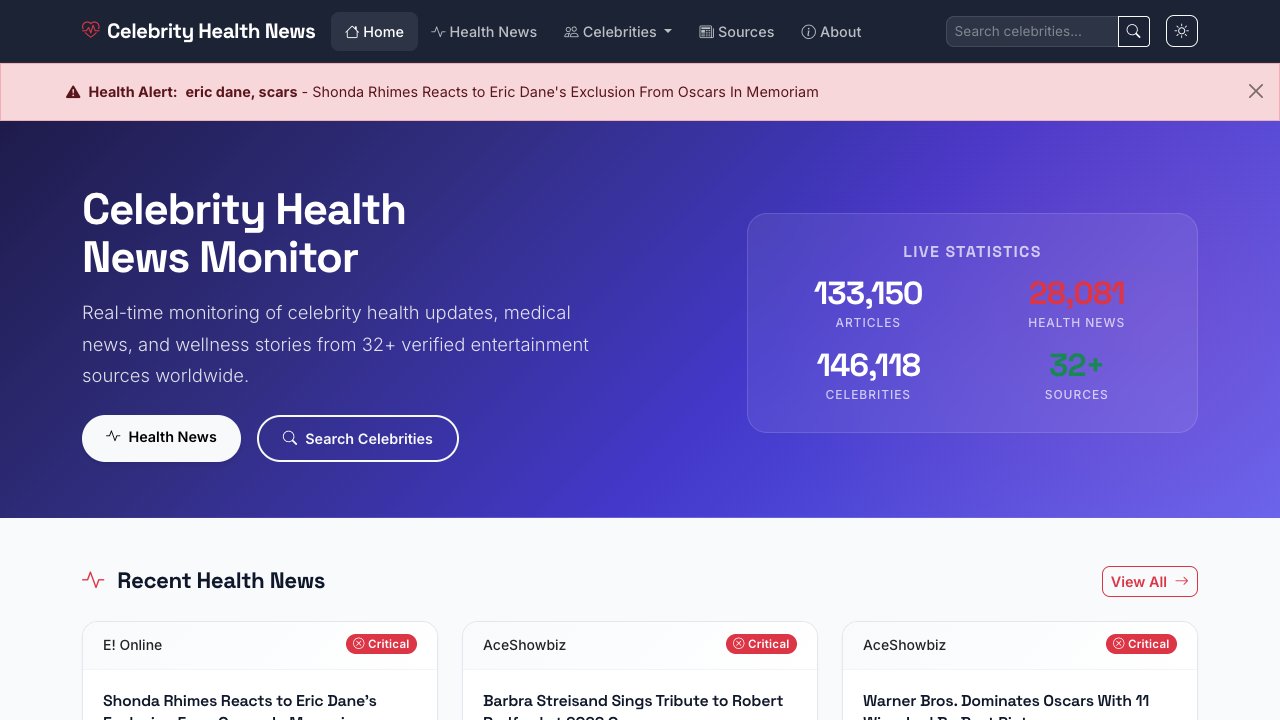
CelebrityMention

CelebrityMention.com

Real-time celebrity-news intelligence. Ingests articles from 30+ feeds, embeds them with NVIDIA NIM models, and matches each story to the right person via pgvector vector-similarity search across 76K+ articles and 22K+ embedded entities — with a dominance gate to eliminate false positives. Includes PodTalk, a YouTube-transcript pipeline that extracts verbatim quotes with automated fact-checking (94% exact, zero fabrication).

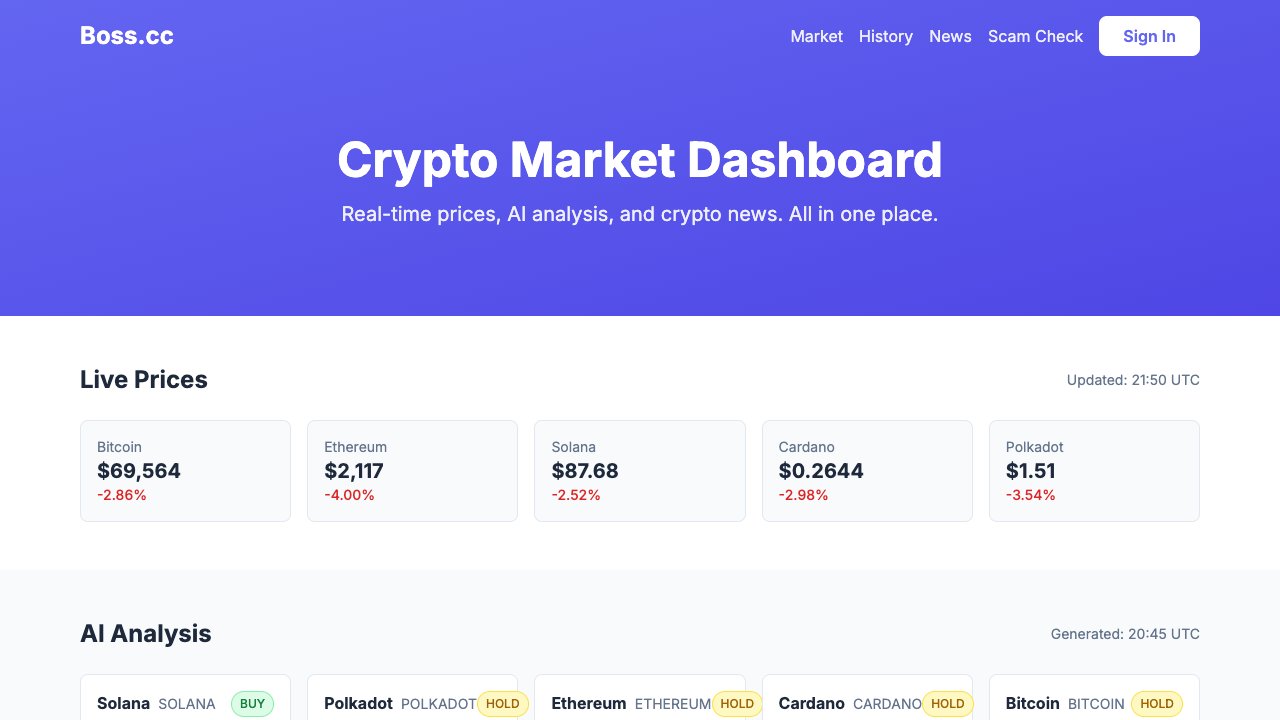
Boss.cc

Boss.cc

Multi-model AI evaluation platform that validates startup ideas by orchestrating an ensemble of five large language models (Llama-4 Maverick, Qwen3-Next 80B, Mistral Medium 3.5, and NVIDIA Nemotron 30B/49B reasoning models) across five assessment lenses — feasibility, market sizing, competition, unit economics, and risk — with an LLM synthesis judge producing a GO / PIVOT / NO-GO verdict in ~10 seconds.

Behind it runs an automated discovery pipeline: hourly Airflow DAGs ingest Stack Exchange, Hacker News, Lobsters and Dev.to, embed and dedup with pgvector, extract and TRIZ-score candidate ideas, then auto-publish the strongest — with provider failover across the model chain and a weekly literary-voice digest.

ClaimLens

ClaimLens

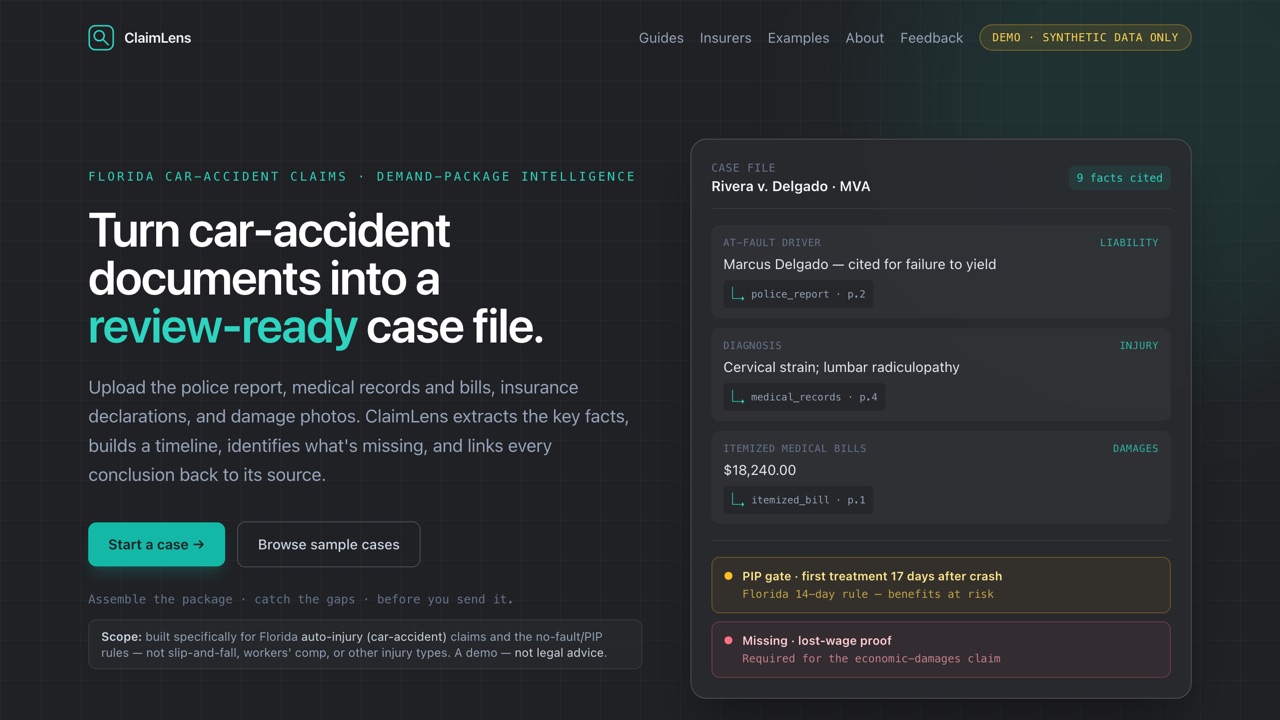
Multimodal case-file builder for Florida no-fault (PIP) car-accident claims. It ingests police reports, medical records and itemized bills, insurance declarations, and crash photos, then fills a typed demand-package schema — parties, liability, injuries, damages, lost income, coverage — instead of returning a pile of RAG Q&A. A vision model reads damage and injury photographs into structured findings, not just the text documents.

A chronology engine assembles dated events into one timeline and flags Florida's hard statutory gates — the 14-day PIP treatment rule and the 30-day insurer window — while a checklist engine detects missing documents (radiology, lost-wage proof, liens) before the package is sent. Every conclusion links back to its source page or photo, and the whole package exports as a cited PDF. Demo on synthetic data, running on free local models.

BookkeeperLens

BookkeeperLens

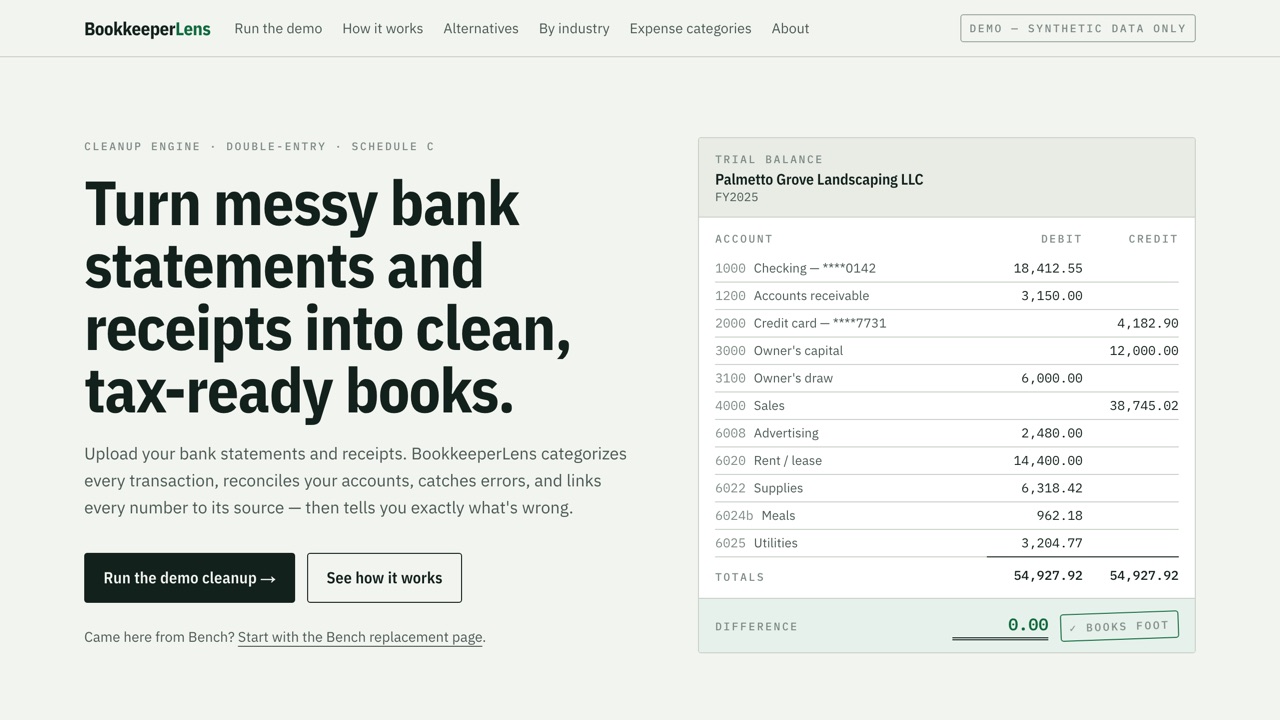
Bookkeeping cleanup engine that turns messy bank statements and a shoebox of receipts into double-entry, Schedule C-ready books — in five stages: upload (PDF/CSV statements plus receipt photos, no bank linking), extract (every statement line becomes a transaction that keeps its page and line provenance; a vision model reads receipts into vendor, date, tax and total), categorize (a Schedule C account with a confidence score and the reason it was chosen, with likely-personal spend flagged instead of deducted), reconcile (each month checked against the statement's ending balance, each receipt matched to the bank line that paid it), and report.

Output is a tax-readiness score out of 100, a prioritized fix list, a P&L and balance sheet, and a trial balance that foots to zero — catching duplicates, miscategorizations, stale uncleared items and missing receipts along the way, with every number traceable to the paper it came from. Built as a self-serve path off outsourced bookkeeping (Bench), running on the free NVIDIA NIM tier or fully private via Ollama.

AllMyQuotes

AllMyQuotes.com

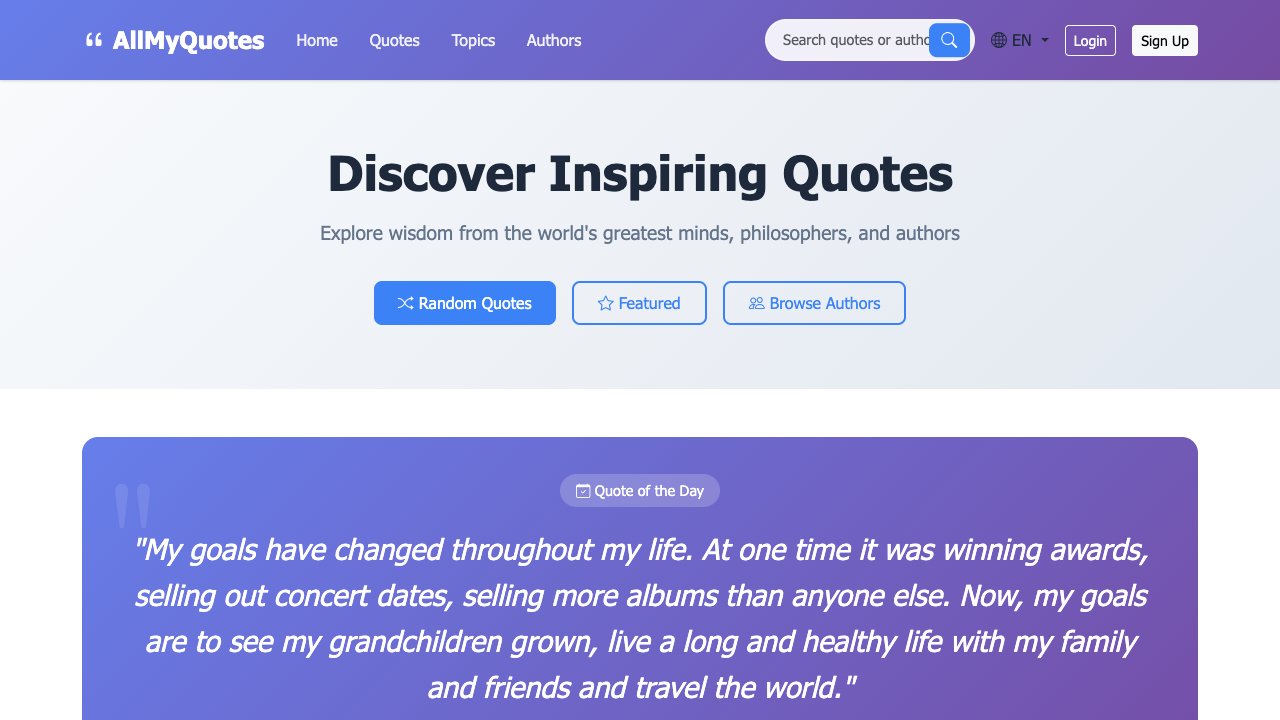
AI quote-discovery platform serving 3M+ quotes from 100K+ authors, fully vectorized with embeddings to power semantic search and similarity matching. Runs an ML pipeline with local LLM inference (Ollama) for classification and sentiment analysis, plus an automated translation pipeline localizing the corpus across 6 languages (English, Spanish, Russian, Tagalog, Vietnamese, Chinese). Multi-server architecture with dedicated GPU processing for embedding and ETL workloads.

Laurela

Laurela.com

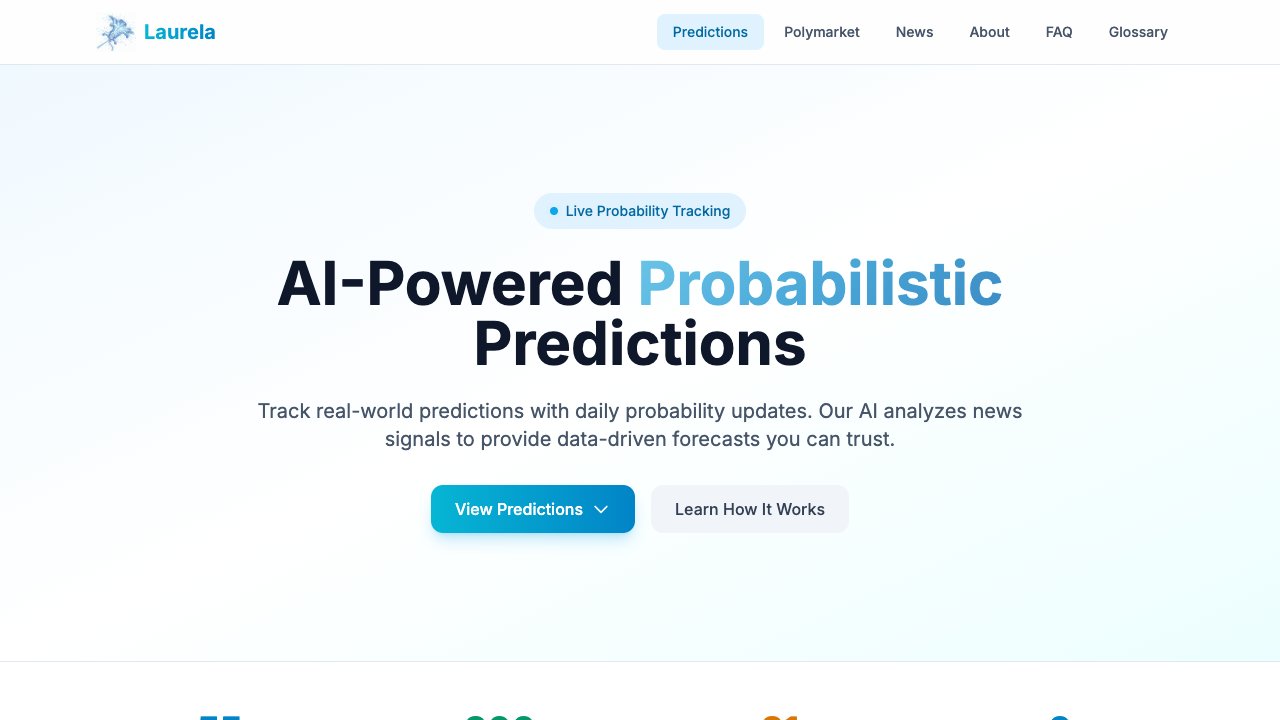
Production document-ordering platform for apostille & notarized-translation services. 56 document types with dynamic forms, cart and guest/OTP checkout via Stripe, auto-generated invoices and order references, an admin order desk, and Telegram alerts — on a Next.js/PostgreSQL stack with full SEO architecture (per-document pages, sitemap, JSON-LD).

Kargin-Utkin

Kargin-Utkin.com

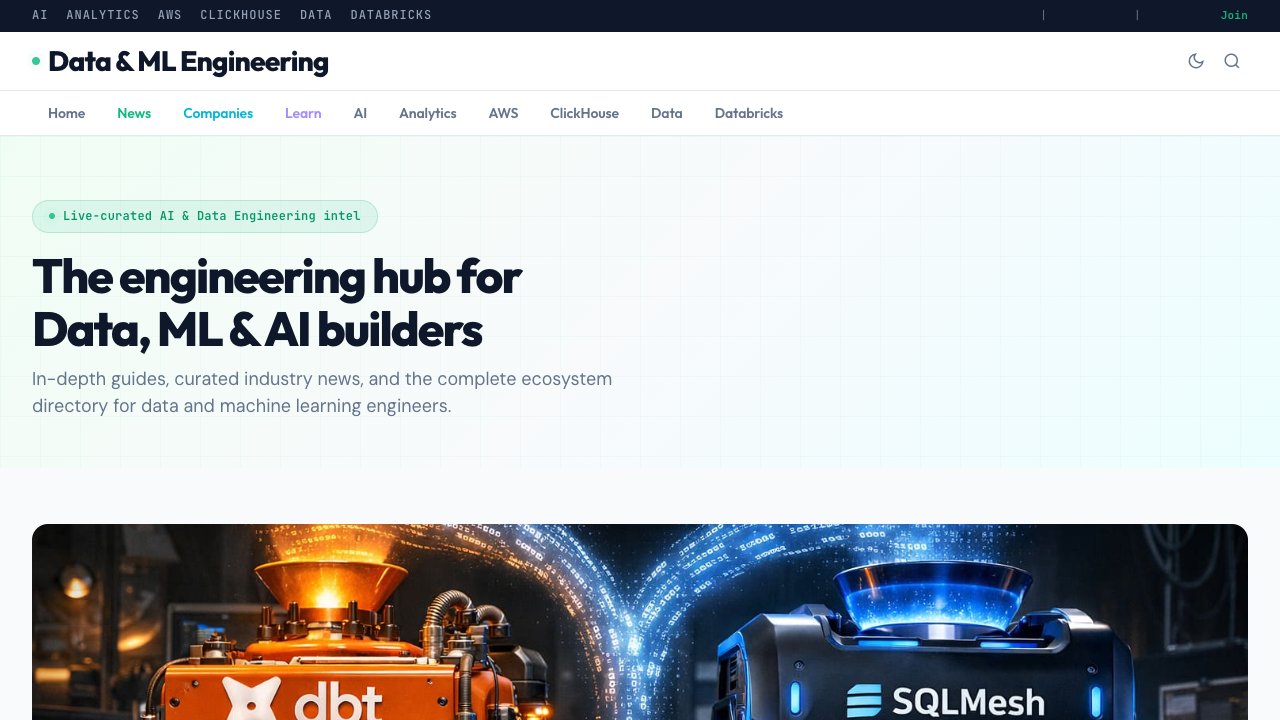
Data & ML engineering hub with technical guides on ETL pipelines, vector databases, GPU analytics, and lakehouse architecture. Features curated AI/data industry news, tool comparisons, and an ecosystem directory of 23+ categories across the modern data stack.

Deep dives: ClickHouse · Snowflake · AWS

Story Digest

Story Digest

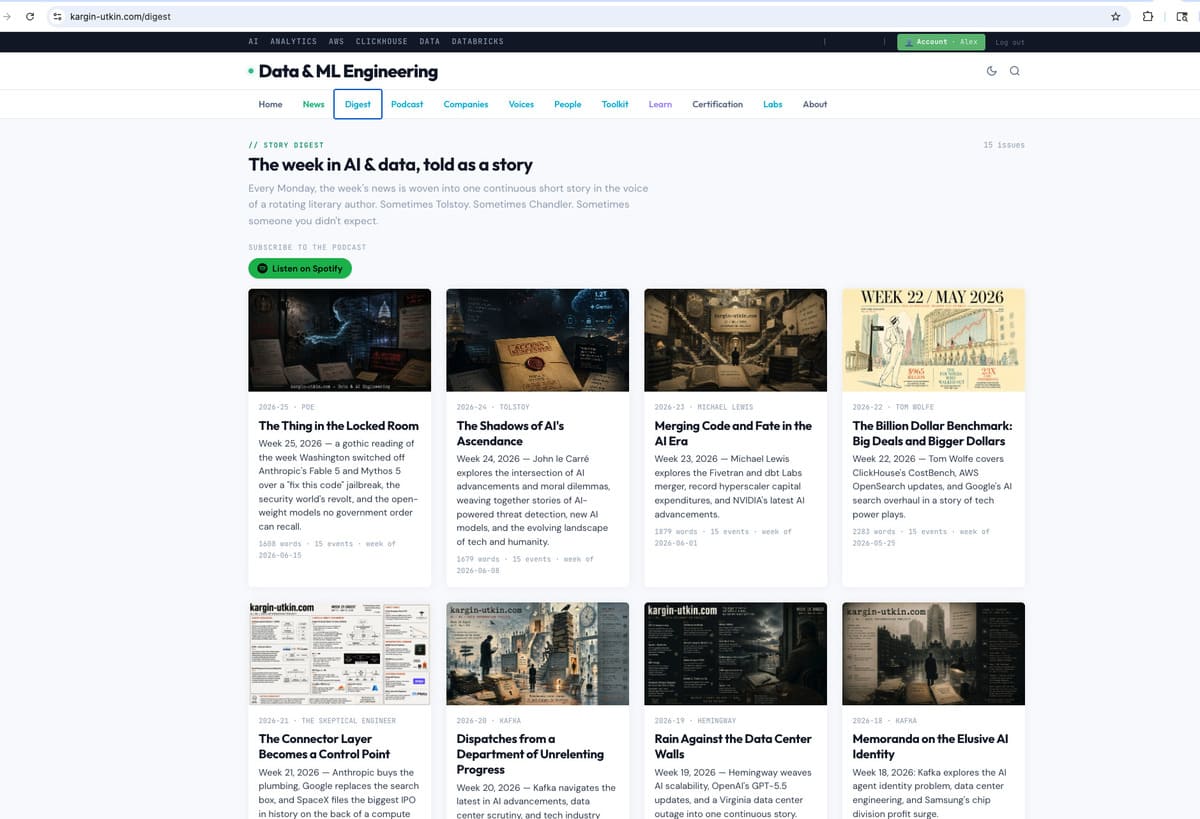
Automated LLM content pipeline that ingests ~15 weekly AI, ML, and data-engineering events, performs topic extraction and clustering, then uses prompt-engineered generation to synthesize them into a single long-form narrative in rotating literary author voices (Tolstoy, Hemingway, Kafka). Scheduled weekly run with RSS feed ingestion, NLP summarization, and email/RSS distribution — 11 issues published.

Daily AI Brief

Daily AI Brief

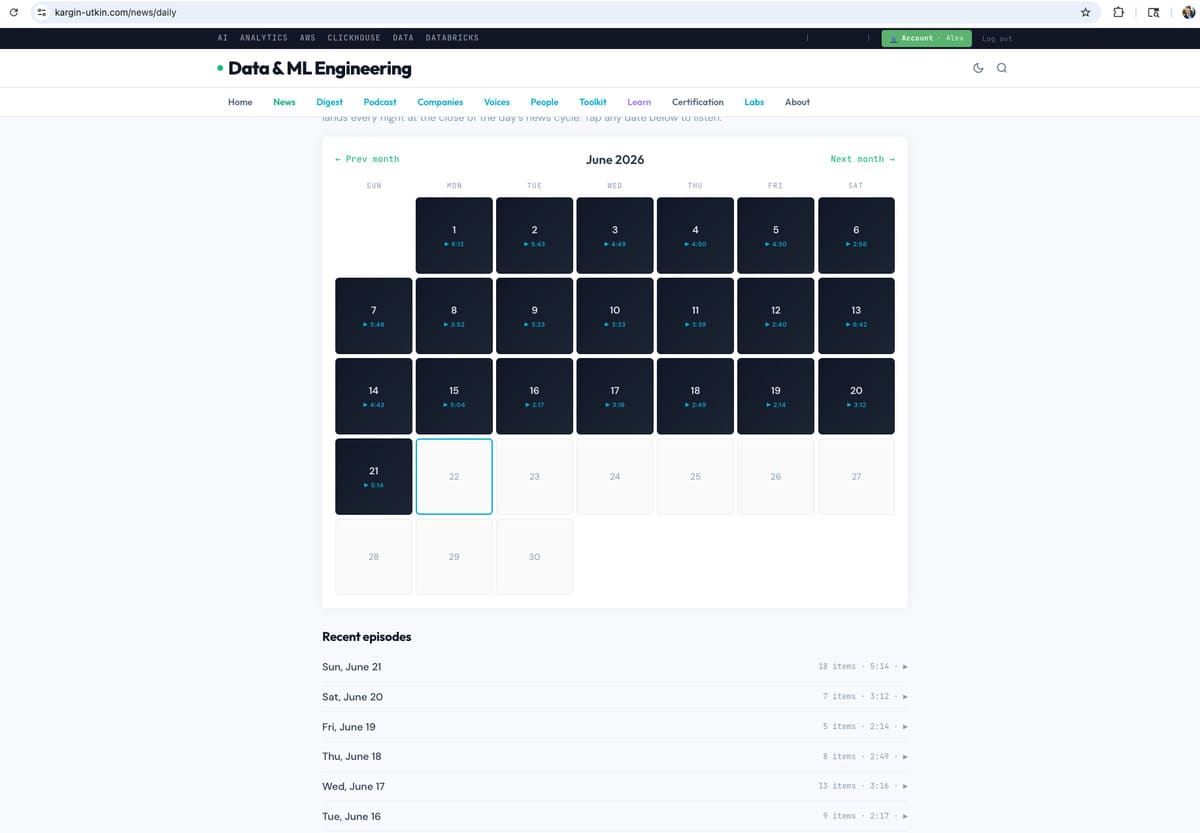
An automated daily Data & AI news pipeline: ingests stories from many sources, analyzes and clusters them, then synthesizes and narrates a short audio briefing engineers can listen to on the commute — published every evening with a calendar of past episodes.

FreeDiva

FreeDiva.com

AI-powered personal styling platform that analyzes body type, skin tone, and proportions from uploaded photos to generate tailored outfit recommendations. Features a chat stylist interface, body shape classification, and shoppable outfit suggestions.

Notes

Write-ups and reference material I put together while working, published in case they save someone else the time.

  • Code with Claude 2026 — all 19 talks, summarized

    Anthropic’s developer conference ran to 8 hours and 23 minutes of video. I transcribed all 19 talks and compressed each into a few sentences, with direct links — so you can watch the four that matter and skip the rest.

Ask about Alex
Hi! Ask me about Alex's skills, projects, or experience.